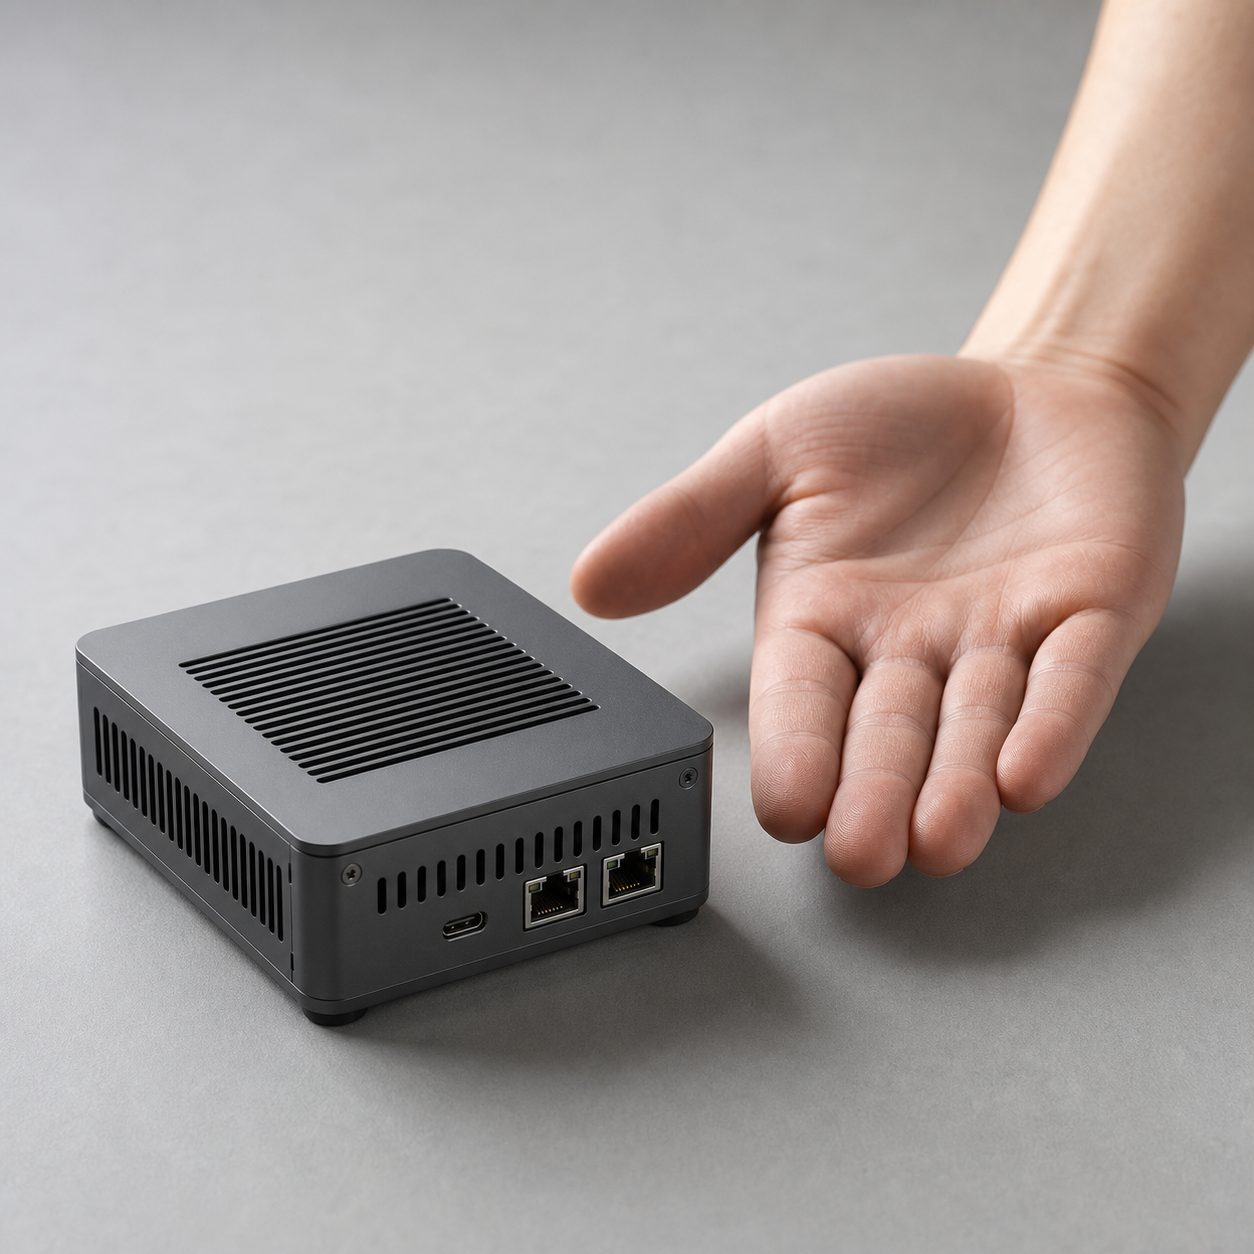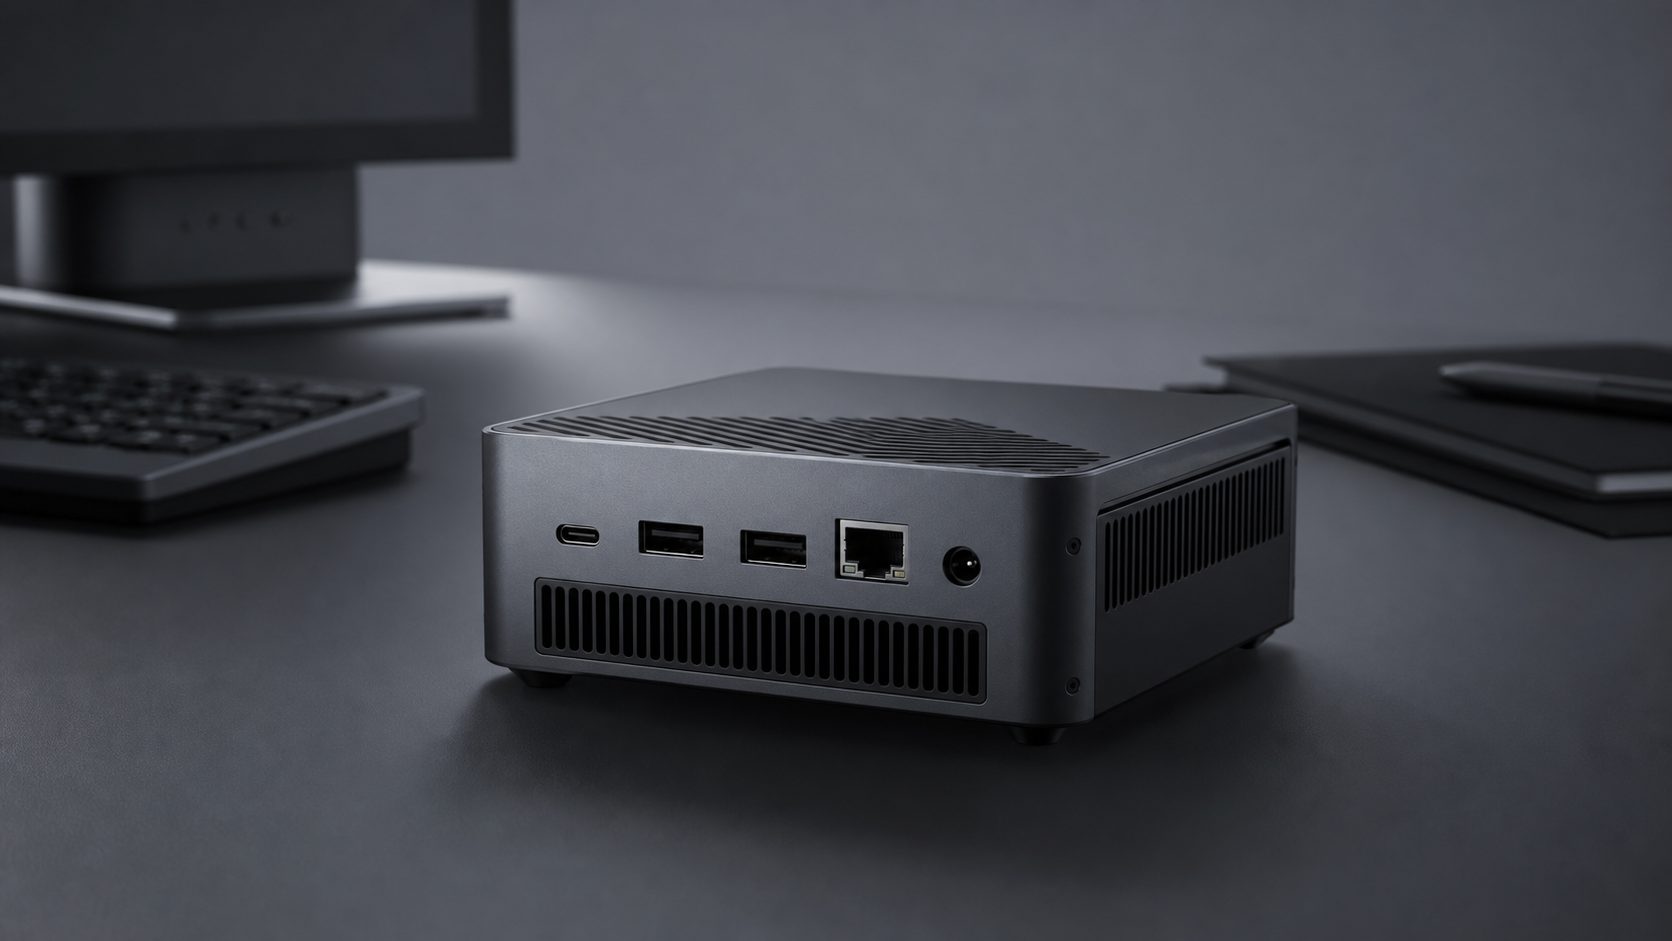
gpuvera terminal on a desk — concept render, pre-production.

gpuvera.

Run models on your desk,
not someone’s cloud.

A palm-sized inference terminal.
Plug it in. Load a model. Make it yours.

Concept render · pre-production.
Not a photo of a shipping unit.

Join the waitlist ↗
01 / WHY LOCAL

Your model.
Your data.
Your electricity.
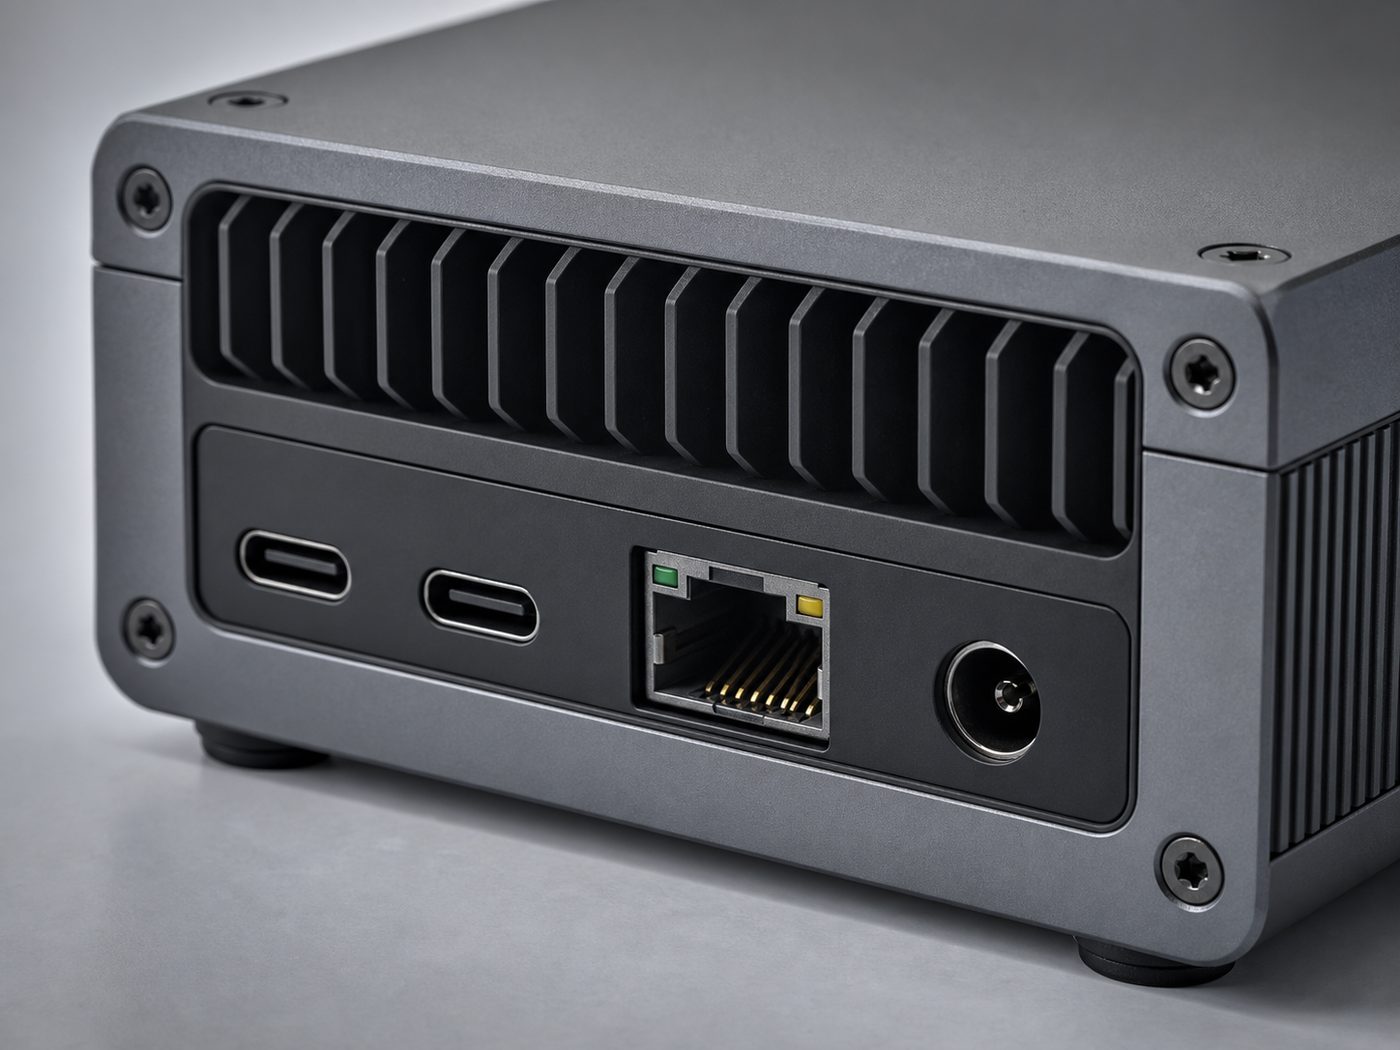
gpuvera ports and cooling details — concept render.
Concept render · pre-production. Final hardware may differ.

Keep the whole loop on your desk.

Private by default

Prompts and files never leave the device unless you send them.

Works offline

Once a model is loaded, gpuvera runs with the network unplugged.

You own the compute

Buy it once. No per-token billing. The hardware is yours.
See full specs ↗
02 / MAKE IT YOURS

Three steps.
Then it’s just there.

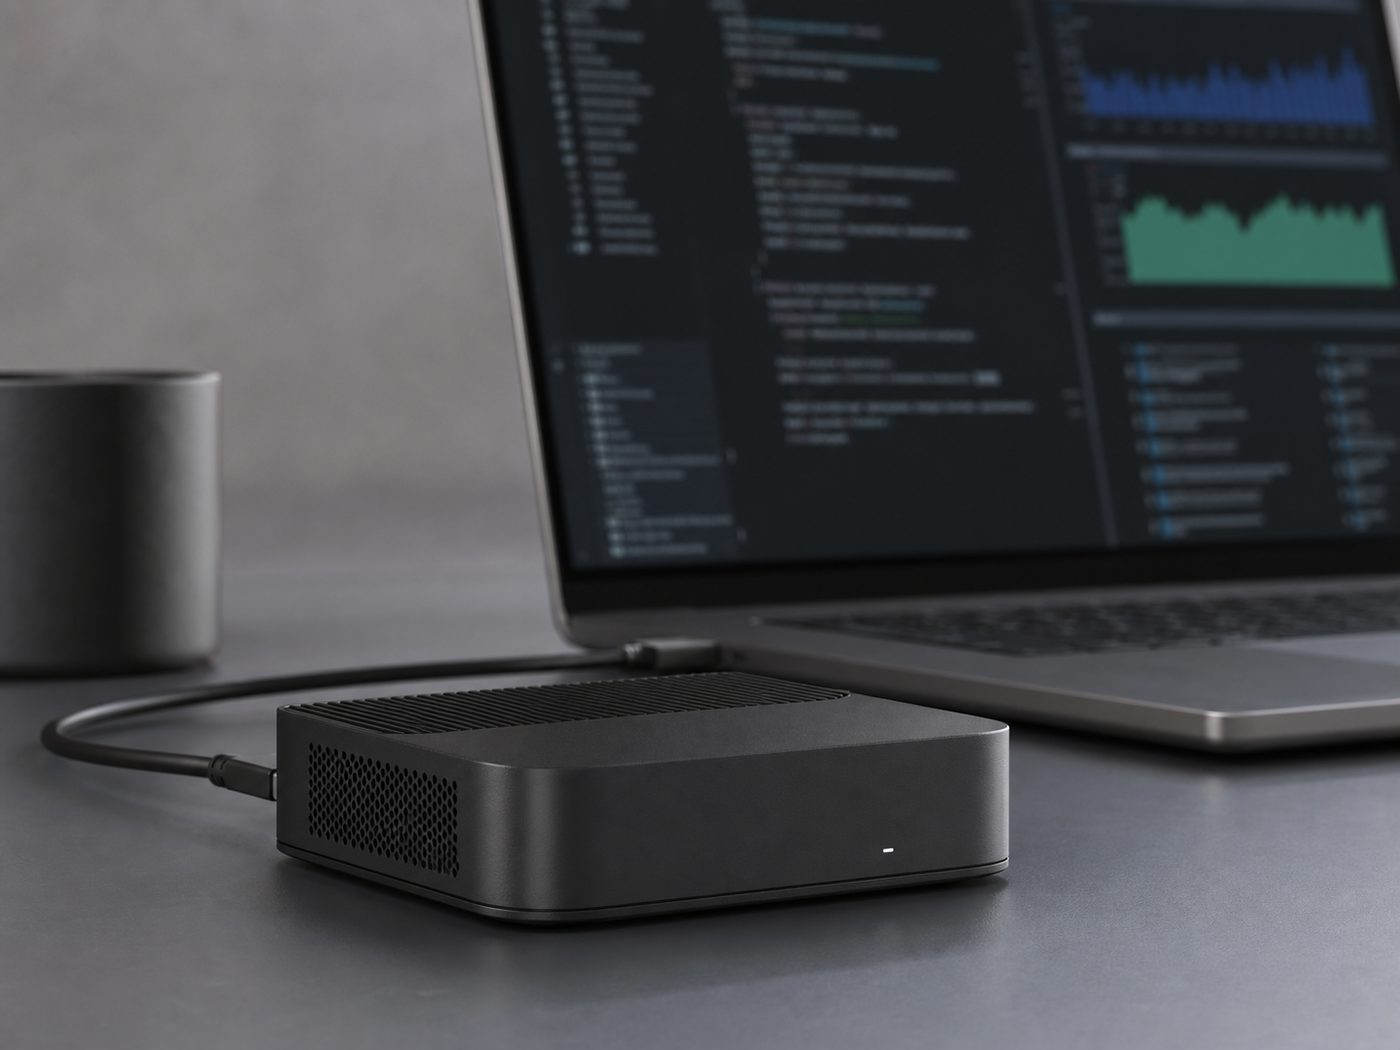
gpuvera beside a laptop with a local model console — concept render, pre-production.
Concept render · pre-production. Not a photo of a shipping unit.

Plug it in

It sits next to your monitor, not in a server rack. Connect the terminal to your own network.

Load a model

Open the local console in your browser and pull an open-weight model — chat, code, or vision. It stays on-device for next time.

Prompt it

Your laptop, phone, or another workstation talks to gpuvera over your LAN.

Explore the local workflow ↗
03 / BUILT FOR YOUR DESK

One small box.
A whole room
of possibilities.

A palm-sized terminal for the open-weight models people run locally. Your devices share one box over your own network.

See the hardware targets ↗
gpuvera terminal next to a hand for scale — concept render, pre-production.
Concept render · pre-production. Final dimensions remain targets.
04 / WHAT WE’RE BUILDING

It’s early.
We’ll say what
is real.

These are pre-production units. Figures marked target are engineering goals, not independently verified measurements.

Every throughput number will ship with the model, quantization, and prompt length it was measured at.

Model classOpen-weight · sized to fit
Model memoryTarget · not finalized
Inference acceleratorTo be determined
Local HTTP endpointOpenAI-compatible · target
Pricing & ship windowWaitlist updates
Read the complete spec sheet ↗

A little clarity.

What models is it for?

Open-weight chat, code and vision models, sized to its on-device memory. Frontier cluster-scale models are not the goal. Exact sizes are targets on the specs page.

Is this shipping hardware?

These are pre-production units. The images are concept renders, not photos of a shipping unit; final hardware may differ.

How do I hear about availability?

Join the waitlist for pricing, ship window, and refund terms as they firm up. No charge to reserve.

Keep it on your desk.

Join the waitlist for pricing, ship window, and refund terms.

Join the waitlist ↗